Winning Gold at the IPhO
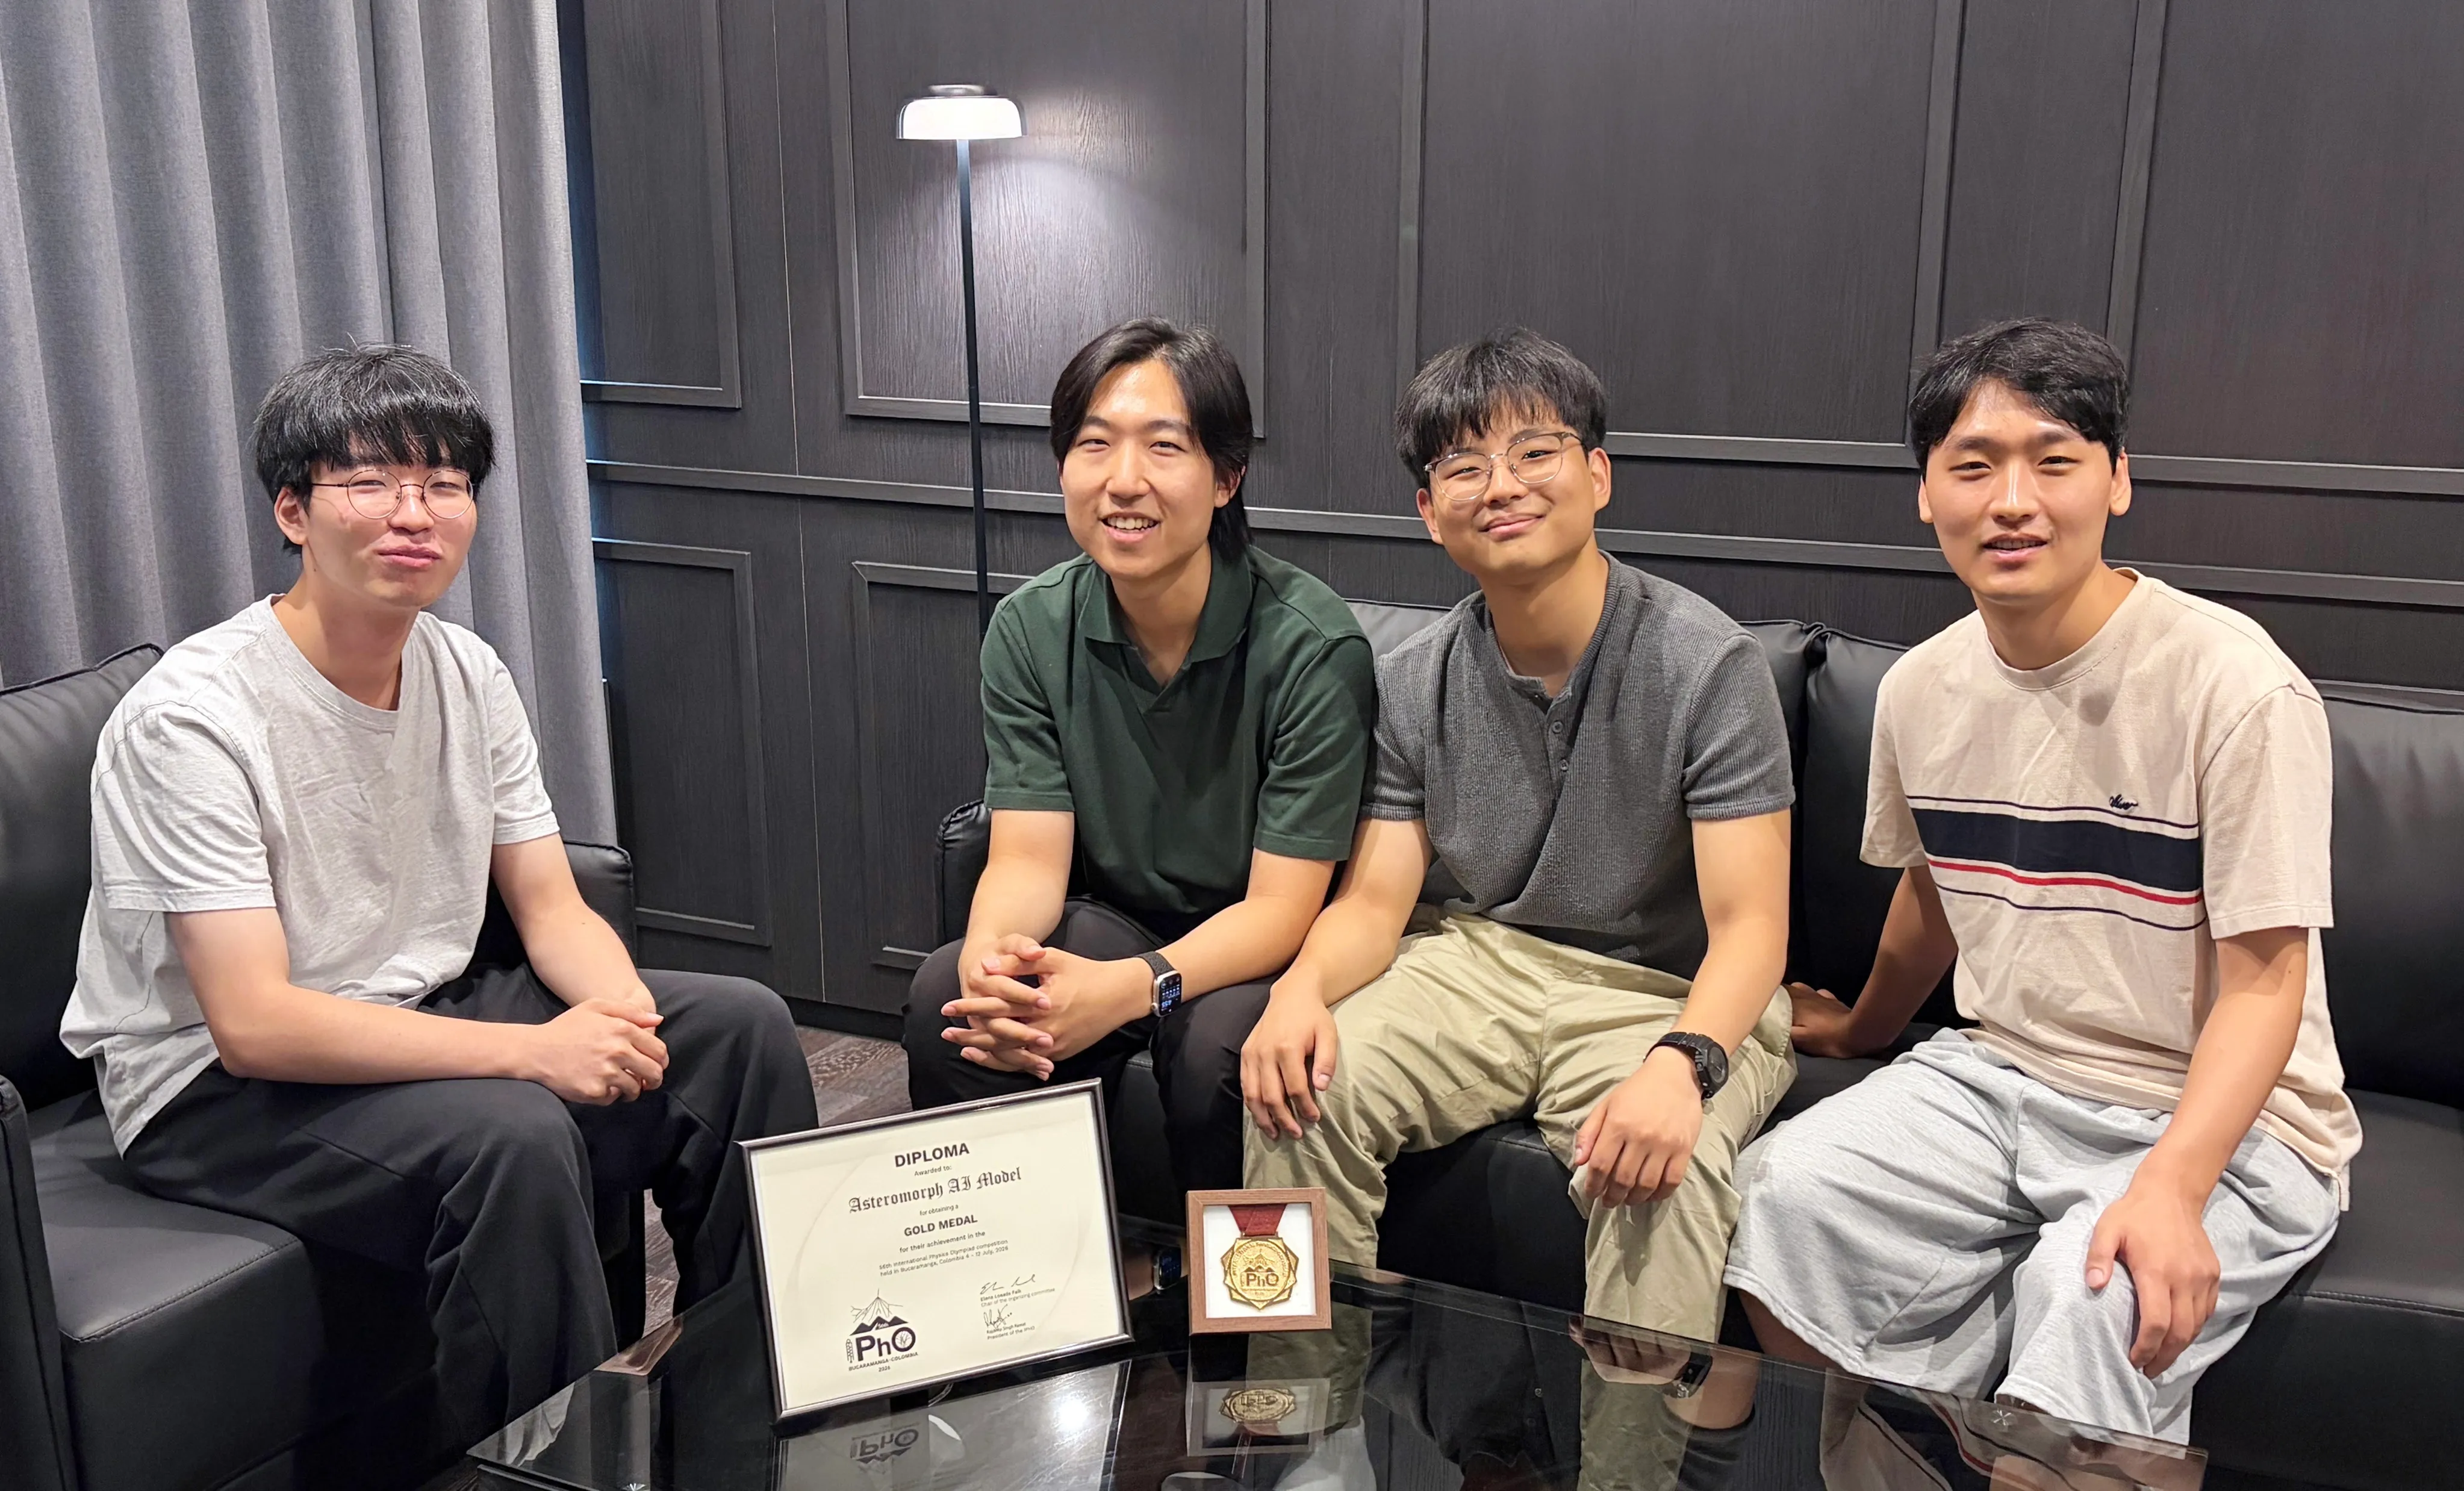
On July 8th, 2026, our AI system took the theory exam of the 56th International Physics Olympiad (IPhO) in Bucaramanga, Colombia. Our engineers traveled to Colombia to allow it to take the exam live during the same five-hour window as every other contestant, from 9:10 AM to 2:10 PM. The system was enclosed in an isolated environment, with no internet or access to external models. 2 days later, the official IPhO graders returned with our score: 28.6 points out of 30, a gold-medal performance. The IPhO committee formally recognized our results in the following month, issuing an official diploma in our name.
Why the IPhO?
We believe that scientific research depends on two broad capabilities: research intuition and raw problem-solving ability.
Research intuition is the ability to decide what to try, such as determining which questions matter, which hypotheses are promising, or how to make progress when there is no well-defined path forward. In our previous work with Thyla 1.0, we found that an agentic system built around open-weight models could already perform at the level of frontier models on open-ended research.
This left us wanting to understand how far similar agentic systems built on open-weight models could perform on tasks that primarily test raw intelligence, compared to frontier models.
The IPhO was our method to test that, as its theory exam is substantially difficult and graded against a fixed standard. Unlike an open-ended research benchmark, the objective is to solve well-defined physics problems correctly, under time pressure with no external information. With these conditions, we wanted to see how far an open-weight model could go when placed inside another agentic system.
How the system works
Our system was built as a fully autonomous agentic framework, with its core reasoning loop built on the open-weight Qwen3.5-397B-A17B model. Three key properties shaped our design:
- End-to-end. The framework operates the entire pipeline, including input PDF scanning, reasoning, self-verification, peer review, and output PDF typesetting.
- Fully isolated execution. Reasoning branches run within their own disposable sandbox, allowing model-written code to be executed freely without ever touching the host or another branch.
- Isolated and offline. The entire system runs entirely on self-hosted open-weight models, in an isolated environment with no internet access.
The system ran on AWS cloud infrastructure, in an isolated environment with no internet access. Within this environment, our pipeline orchestrated multiple self-hosted models, each taking on different roles to contribute to a final solution.
Isolation ensured that neither the exam nor the intermediate reasoning ever left our environment, making it suitable to process sensitive or embargoed material without relying on a third party vendor. Self-hosted pinned models also made our runs reproducible, insulating the system from unexpected upstream changes.
'%20stroke='rgb(0%2c0%2c0%2c%200.5)'%20width='455'%20height='1228'%20class='rect'/%3e%3ctext%20x='1241.5'%20y='13.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='text'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='1241.5'%20dy='0'%3eSandbox%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect%20x='254'%20y='-5'%20fill='rgba(92%2c%2088%2c%2039%2c%200.18)'%20stroke='rgb(0%2c0%2c0%2c%200.5)'%20width='725'%20height='1228'%20class='rect'/%3e%3ctext%20x='616.5'%20y='13.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='text'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='616.5'%20dy='0'%3eGPU%20Node%3c/tspan%3e%3c/text%3e%3c/g%3e%3crect%20x='42.5'%20y='1007'%20fill='rgba(94%2c%2087%2c%20150%2c%200.14)'%20width='364'%20height='111'%20class='rect'/%3e%3crect%20x='321.5'%20y='523'%20fill='rgba(164%2c%2068%2c%2068%2c%200.14)'%20width='1080'%20height='474'%20class='rect'/%3e%3crect%20x='321.5'%20y='358'%20fill='rgba(44%2c%20130%2c%2086%2c%200.14)'%20width='590'%20height='155'%20class='rect'/%3e%3crect%20x='321.5'%20y='193'%20fill='rgba(173%2c%20116%2c%2043%2c%200.14)'%20width='355'%20height='155'%20class='rect'/%3e%3cg%3e%3crect%20x='1274'%20y='1138'%20fill='%23eaeaea'%20stroke='%23666'%20width='170'%20height='65'%20name='T'%20rx='3'%20ry='3'%20class='actor%20actor-bottom'/%3e%3ctext%20x='1359'%20y='1170.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-box'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='1359'%20dy='0'%3eScience%20Tools%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect%20x='1039'%20y='1138'%20fill='%23eaeaea'%20stroke='%23666'%20width='170'%20height='65'%20name='S'%20rx='3'%20ry='3'%20class='actor%20actor-bottom'/%3e%3ctext%20x='1124'%20y='1170.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-box'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='1124'%20dy='0'%3eSandbox%20API%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect%20x='784'%20y='1138'%20fill='%23eaeaea'%20stroke='%23666'%20width='170'%20height='65'%20name='G'%20rx='3'%20ry='3'%20class='actor%20actor-bottom'/%3e%3ctext%20x='869'%20y='1170.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-box'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='869'%20dy='0'%3eSGLang%20servers%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect%20x='549'%20y='1138'%20fill='%23eaeaea'%20stroke='%23666'%20width='170'%20height='65'%20name='O'%20rx='3'%20ry='3'%20class='actor%20actor-bottom'/%3e%3ctext%20x='634'%20y='1170.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-box'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='634'%20dy='0'%3eOCR%20server%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect%20x='279'%20y='1138'%20fill='%23eaeaea'%20stroke='%23666'%20width='170'%20height='65'%20name='A'%20rx='3'%20ry='3'%20class='actor%20actor-bottom'/%3e%3ctext%20x='364'%20y='1170.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-box'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='364'%20dy='0'%3eAgent%20Core%20(Rust)%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg/%3e%3cg%3e%3cline%20id='actor5'%20x1='1359'%20y1='92'%20x2='1359'%20y2='1138'%20class='actor-line%20200'%20stroke-width='0.5px'%20stroke='%23999'%20name='T'/%3e%3cg%20id='root-5'%3e%3crect%20x='1274'%20y='27'%20fill='%23eaeaea'%20stroke='%23666'%20width='170'%20height='65'%20name='T'%20rx='3'%20ry='3'%20class='actor%20actor-top'/%3e%3ctext%20x='1359'%20y='59.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-box'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='1359'%20dy='0'%3eScience%20Tools%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/g%3e%3cg%3e%3cline%20id='actor4'%20x1='1124'%20y1='92'%20x2='1124'%20y2='1138'%20class='actor-line%20200'%20stroke-width='0.5px'%20stroke='%23999'%20name='S'/%3e%3cg%20id='root-4'%3e%3crect%20x='1039'%20y='27'%20fill='%23eaeaea'%20stroke='%23666'%20width='170'%20height='65'%20name='S'%20rx='3'%20ry='3'%20class='actor%20actor-top'/%3e%3ctext%20x='1124'%20y='59.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-box'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='1124'%20dy='0'%3eSandbox%20API%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/g%3e%3cg%3e%3cline%20id='actor3'%20x1='869'%20y1='92'%20x2='869'%20y2='1138'%20class='actor-line%20200'%20stroke-width='0.5px'%20stroke='%23999'%20name='G'/%3e%3cg%20id='root-3'%3e%3crect%20x='784'%20y='27'%20fill='%23eaeaea'%20stroke='%23666'%20width='170'%20height='65'%20name='G'%20rx='3'%20ry='3'%20class='actor%20actor-top'/%3e%3ctext%20x='869'%20y='59.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-box'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='869'%20dy='0'%3eSGLang%20servers%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/g%3e%3cg%3e%3cline%20id='actor2'%20x1='634'%20y1='92'%20x2='634'%20y2='1138'%20class='actor-line%20200'%20stroke-width='0.5px'%20stroke='%23999'%20name='O'/%3e%3cg%20id='root-2'%3e%3crect%20x='549'%20y='27'%20fill='%23eaeaea'%20stroke='%23666'%20width='170'%20height='65'%20name='O'%20rx='3'%20ry='3'%20class='actor%20actor-top'/%3e%3ctext%20x='634'%20y='59.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-box'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='634'%20dy='0'%3eOCR%20server%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/g%3e%3cg%3e%3cline%20id='actor1'%20x1='364'%20y1='92'%20x2='364'%20y2='1138'%20class='actor-line%20200'%20stroke-width='0.5px'%20stroke='%23999'%20name='A'/%3e%3cg%20id='root-1'%3e%3crect%20x='279'%20y='27'%20fill='%23eaeaea'%20stroke='%23666'%20width='170'%20height='65'%20name='A'%20rx='3'%20ry='3'%20class='actor%20actor-top'/%3e%3ctext%20x='364'%20y='59.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-box'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='364'%20dy='0'%3eAgent%20Core%20(Rust)%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/g%3e%3cg%3e%3cline%20id='actor0'%20x1='85'%20y1='107'%20x2='85'%20y2='1138'%20class='actor-line%20200'%20stroke-width='0.5px'%20stroke='%23999'%20name='U'/%3e%3c/g%3e%3cstyle%3e%23mermaid-dark-0%7bfont-family:arial%2csans-serif%3bfont-size:16px%3bfill:%23ccc%3b%7d%40keyframes%20edge-animation-frame%7bfrom%7bstroke-dashoffset:0%3b%7d%7d%40keyframes%20dash%7bto%7bstroke-dashoffset:0%3b%7d%7d%23mermaid-dark-0%20.edge-animation-slow%7bstroke-dasharray:9%2c5!important%3bstroke-dashoffset:900%3banimation:dash%2050s%20linear%20infinite%3bstroke-linecap:round%3b%7d%23mermaid-dark-0%20.edge-animation-fast%7bstroke-dasharray:9%2c5!important%3bstroke-dashoffset:900%3banimation:dash%2020s%20linear%20infinite%3bstroke-linecap:round%3b%7d%23mermaid-dark-0%20.error-icon%7bfill:%23a44141%3b%7d%23mermaid-dark-0%20.error-text%7bfill:%23ddd%3bstroke:%23ddd%3b%7d%23mermaid-dark-0%20.edge-thickness-normal%7bstroke-width:1px%3b%7d%23mermaid-dark-0%20.edge-thickness-thick%7bstroke-width:3.5px%3b%7d%23mermaid-dark-0%20.edge-pattern-solid%7bstroke-dasharray:0%3b%7d%23mermaid-dark-0%20.edge-thickness-invisible%7bstroke-width:0%3bfill:none%3b%7d%23mermaid-dark-0%20.edge-pattern-dashed%7bstroke-dasharray:3%3b%7d%23mermaid-dark-0%20.edge-pattern-dotted%7bstroke-dasharray:2%3b%7d%23mermaid-dark-0%20.marker%7bfill:lightgrey%3bstroke:lightgrey%3b%7d%23mermaid-dark-0%20.marker.cross%7bstroke:lightgrey%3b%7d%23mermaid-dark-0%20svg%7bfont-family:arial%2csans-serif%3bfont-size:16px%3b%7d%23mermaid-dark-0%20p%7bmargin:0%3b%7d%23mermaid-dark-0%20.actor%7bstroke:%23ccc%3bfill:%231f2020%3b%7d%23mermaid-dark-0%20text.actor%26gt%3btspan%7bfill:lightgrey%3bstroke:none%3b%7d%23mermaid-dark-0%20.actor-line%7bstroke:%23ccc%3b%7d%23mermaid-dark-0%20.innerArc%7bstroke-width:1.5%3bstroke-dasharray:none%3b%7d%23mermaid-dark-0%20.messageLine0%7bstroke-width:1.5%3bstroke-dasharray:none%3bstroke:lightgrey%3b%7d%23mermaid-dark-0%20.messageLine1%7bstroke-width:1.5%3bstroke-dasharray:2%2c2%3bstroke:lightgrey%3b%7d%23mermaid-dark-0%20%23arrowhead%20path%7bfill:lightgrey%3bstroke:lightgrey%3b%7d%23mermaid-dark-0%20.sequenceNumber%7bfill:black%3b%7d%23mermaid-dark-0%20%23sequencenumber%7bfill:lightgrey%3b%7d%23mermaid-dark-0%20%23crosshead%20path%7bfill:lightgrey%3bstroke:lightgrey%3b%7d%23mermaid-dark-0%20.messageText%7bfill:lightgrey%3bstroke:none%3b%7d%23mermaid-dark-0%20.labelBox%7bstroke:%23ccc%3bfill:%231f2020%3b%7d%23mermaid-dark-0%20.labelText%2c%23mermaid-dark-0%20.labelText%26gt%3btspan%7bfill:lightgrey%3bstroke:none%3b%7d%23mermaid-dark-0%20.loopText%2c%23mermaid-dark-0%20.loopText%26gt%3btspan%7bfill:lightgrey%3bstroke:none%3b%7d%23mermaid-dark-0%20.loopLine%7bstroke-width:2px%3bstroke-dasharray:2%2c2%3bstroke:%23ccc%3bfill:%23ccc%3b%7d%23mermaid-dark-0%20.note%7bstroke:hsl(180%2c%200%25%2c%2018.3529411765%25)%3bfill:hsl(180%2c%201.5873015873%25%2c%2028.3529411765%25)%3b%7d%23mermaid-dark-0%20.noteText%2c%23mermaid-dark-0%20.noteText%26gt%3btspan%7bfill:rgb(183.8476190475%2c%20181.5523809523%2c%20181.5523809523)%3bstroke:none%3b%7d%23mermaid-dark-0%20.activation0%7bfill:hsl(180%2c%201.5873015873%25%2c%2028.3529411765%25)%3bstroke:%23ccc%3b%7d%23mermaid-dark-0%20.activation1%7bfill:hsl(180%2c%201.5873015873%25%2c%2028.3529411765%25)%3bstroke:%23ccc%3b%7d%23mermaid-dark-0%20.activation2%7bfill:hsl(180%2c%201.5873015873%25%2c%2028.3529411765%25)%3bstroke:%23ccc%3b%7d%23mermaid-dark-0%20.actorPopupMenu%7bposition:absolute%3b%7d%23mermaid-dark-0%20.actorPopupMenuPanel%7bposition:absolute%3bfill:%231f2020%3bbox-shadow:0px%208px%2016px%200px%20rgba(0%2c0%2c0%2c0.2)%3bfilter:drop-shadow(3px%205px%202px%20rgb(0%200%200%20/%200.4))%3b%7d%23mermaid-dark-0%20.actor-man%20line%7bstroke:%23ccc%3bfill:%231f2020%3b%7d%23mermaid-dark-0%20.actor-man%20circle%2c%23mermaid-dark-0%20line%7bstroke:%23ccc%3bfill:%231f2020%3bstroke-width:2px%3b%7d%23mermaid-dark-0%20:root%7b--mermaid-font-family:arial%2csans-serif%3b%7d%3c/style%3e%3cg/%3e%3cdefs%3e%3csymbol%20id='computer'%20width='24'%20height='24'%3e%3cpath%20transform='scale(.5)'%20d='M2%202v13h20v-13h-20zm18%2011h-16v-9h16v9zm-10.228%206l.466-1h3.524l.467%201h-4.457zm14.228%203h-24l2-6h2.104l-1.33%204h18.45l-1.297-4h2.073l2%206zm-5-10h-14v-7h14v7z'/%3e%3c/symbol%3e%3c/defs%3e%3cdefs%3e%3csymbol%20id='database'%20fill-rule='evenodd'%20clip-rule='evenodd'%3e%3cpath%20transform='scale(.5)'%20d='M12.258.001l.256.004.255.005.253.008.251.01.249.012.247.015.246.016.242.019.241.02.239.023.236.024.233.027.231.028.229.031.225.032.223.034.22.036.217.038.214.04.211.041.208.043.205.045.201.046.198.048.194.05.191.051.187.053.183.054.18.056.175.057.172.059.168.06.163.061.16.063.155.064.15.066.074.033.073.033.071.034.07.034.069.035.068.035.067.035.066.035.064.036.064.036.062.036.06.036.06.037.058.037.058.037.055.038.055.038.053.038.052.038.051.039.05.039.048.039.047.039.045.04.044.04.043.04.041.04.04.041.039.041.037.041.036.041.034.041.033.042.032.042.03.042.029.042.027.042.026.043.024.043.023.043.021.043.02.043.018.044.017.043.015.044.013.044.012.044.011.045.009.044.007.045.006.045.004.045.002.045.001.045v17l-.001.045-.002.045-.004.045-.006.045-.007.045-.009.044-.011.045-.012.044-.013.044-.015.044-.017.043-.018.044-.02.043-.021.043-.023.043-.024.043-.026.043-.027.042-.029.042-.03.042-.032.042-.033.042-.034.041-.036.041-.037.041-.039.041-.04.041-.041.04-.043.04-.044.04-.045.04-.047.039-.048.039-.05.039-.051.039-.052.038-.053.038-.055.038-.055.038-.058.037-.058.037-.06.037-.06.036-.062.036-.064.036-.064.036-.066.035-.067.035-.068.035-.069.035-.07.034-.071.034-.073.033-.074.033-.15.066-.155.064-.16.063-.163.061-.168.06-.172.059-.175.057-.18.056-.183.054-.187.053-.191.051-.194.05-.198.048-.201.046-.205.045-.208.043-.211.041-.214.04-.217.038-.22.036-.223.034-.225.032-.229.031-.231.028-.233.027-.236.024-.239.023-.241.02-.242.019-.246.016-.247.015-.249.012-.251.01-.253.008-.255.005-.256.004-.258.001-.258-.001-.256-.004-.255-.005-.253-.008-.251-.01-.249-.012-.247-.015-.245-.016-.243-.019-.241-.02-.238-.023-.236-.024-.234-.027-.231-.028-.228-.031-.226-.032-.223-.034-.22-.036-.217-.038-.214-.04-.211-.041-.208-.043-.204-.045-.201-.046-.198-.048-.195-.05-.19-.051-.187-.053-.184-.054-.179-.056-.176-.057-.172-.059-.167-.06-.164-.061-.159-.063-.155-.064-.151-.066-.074-.033-.072-.033-.072-.034-.07-.034-.069-.035-.068-.035-.067-.035-.066-.035-.064-.036-.063-.036-.062-.036-.061-.036-.06-.037-.058-.037-.057-.037-.056-.038-.055-.038-.053-.038-.052-.038-.051-.039-.049-.039-.049-.039-.046-.039-.046-.04-.044-.04-.043-.04-.041-.04-.04-.041-.039-.041-.037-.041-.036-.041-.034-.041-.033-.042-.032-.042-.03-.042-.029-.042-.027-.042-.026-.043-.024-.043-.023-.043-.021-.043-.02-.043-.018-.044-.017-.043-.015-.044-.013-.044-.012-.044-.011-.045-.009-.044-.007-.045-.006-.045-.004-.045-.002-.045-.001-.045v-17l.001-.045.002-.045.004-.045.006-.045.007-.045.009-.044.011-.045.012-.044.013-.044.015-.044.017-.043.018-.044.02-.043.021-.043.023-.043.024-.043.026-.043.027-.042.029-.042.03-.042.032-.042.033-.042.034-.041.036-.041.037-.041.039-.041.04-.041.041-.04.043-.04.044-.04.046-.04.046-.039.049-.039.049-.039.051-.039.052-.038.053-.038.055-.038.056-.038.057-.037.058-.037.06-.037.061-.036.062-.036.063-.036.064-.036.066-.035.067-.035.068-.035.069-.035.07-.034.072-.034.072-.033.074-.033.151-.066.155-.064.159-.063.164-.061.167-.06.172-.059.176-.057.179-.056.184-.054.187-.053.19-.051.195-.05.198-.048.201-.046.204-.045.208-.043.211-.041.214-.04.217-.038.22-.036.223-.034.226-.032.228-.031.231-.028.234-.027.236-.024.238-.023.241-.02.243-.019.245-.016.247-.015.249-.012.251-.01.253-.008.255-.005.256-.004.258-.001.258.001zm-9.258%2020.499v.01l.001.021.003.021.004.022.005.021.006.022.007.022.009.023.01.022.011.023.012.023.013.023.015.023.016.024.017.023.018.024.019.024.021.024.022.025.023.024.024.025.052.049.056.05.061.051.066.051.07.051.075.051.079.052.084.052.088.052.092.052.097.052.102.051.105.052.11.052.114.051.119.051.123.051.127.05.131.05.135.05.139.048.144.049.147.047.152.047.155.047.16.045.163.045.167.043.171.043.176.041.178.041.183.039.187.039.19.037.194.035.197.035.202.033.204.031.209.03.212.029.216.027.219.025.222.024.226.021.23.02.233.018.236.016.24.015.243.012.246.01.249.008.253.005.256.004.259.001.26-.001.257-.004.254-.005.25-.008.247-.011.244-.012.241-.014.237-.016.233-.018.231-.021.226-.021.224-.024.22-.026.216-.027.212-.028.21-.031.205-.031.202-.034.198-.034.194-.036.191-.037.187-.039.183-.04.179-.04.175-.042.172-.043.168-.044.163-.045.16-.046.155-.046.152-.047.148-.048.143-.049.139-.049.136-.05.131-.05.126-.05.123-.051.118-.052.114-.051.11-.052.106-.052.101-.052.096-.052.092-.052.088-.053.083-.051.079-.052.074-.052.07-.051.065-.051.06-.051.056-.05.051-.05.023-.024.023-.025.021-.024.02-.024.019-.024.018-.024.017-.024.015-.023.014-.024.013-.023.012-.023.01-.023.01-.022.008-.022.006-.022.006-.022.004-.022.004-.021.001-.021.001-.021v-4.127l-.077.055-.08.053-.083.054-.085.053-.087.052-.09.052-.093.051-.095.05-.097.05-.1.049-.102.049-.105.048-.106.047-.109.047-.111.046-.114.045-.115.045-.118.044-.12.043-.122.042-.124.042-.126.041-.128.04-.13.04-.132.038-.134.038-.135.037-.138.037-.139.035-.142.035-.143.034-.144.033-.147.032-.148.031-.15.03-.151.03-.153.029-.154.027-.156.027-.158.026-.159.025-.161.024-.162.023-.163.022-.165.021-.166.02-.167.019-.169.018-.169.017-.171.016-.173.015-.173.014-.175.013-.175.012-.177.011-.178.01-.179.008-.179.008-.181.006-.182.005-.182.004-.184.003-.184.002h-.37l-.184-.002-.184-.003-.182-.004-.182-.005-.181-.006-.179-.008-.179-.008-.178-.01-.176-.011-.176-.012-.175-.013-.173-.014-.172-.015-.171-.016-.17-.017-.169-.018-.167-.019-.166-.02-.165-.021-.163-.022-.162-.023-.161-.024-.159-.025-.157-.026-.156-.027-.155-.027-.153-.029-.151-.03-.15-.03-.148-.031-.146-.032-.145-.033-.143-.034-.141-.035-.14-.035-.137-.037-.136-.037-.134-.038-.132-.038-.13-.04-.128-.04-.126-.041-.124-.042-.122-.042-.12-.044-.117-.043-.116-.045-.113-.045-.112-.046-.109-.047-.106-.047-.105-.048-.102-.049-.1-.049-.097-.05-.095-.05-.093-.052-.09-.051-.087-.052-.085-.053-.083-.054-.08-.054-.077-.054v4.127zm0-5.654v.011l.001.021.003.021.004.021.005.022.006.022.007.022.009.022.01.022.011.023.012.023.013.023.015.024.016.023.017.024.018.024.019.024.021.024.022.024.023.025.024.024.052.05.056.05.061.05.066.051.07.051.075.052.079.051.084.052.088.052.092.052.097.052.102.052.105.052.11.051.114.051.119.052.123.05.127.051.131.05.135.049.139.049.144.048.147.048.152.047.155.046.16.045.163.045.167.044.171.042.176.042.178.04.183.04.187.038.19.037.194.036.197.034.202.033.204.032.209.03.212.028.216.027.219.025.222.024.226.022.23.02.233.018.236.016.24.014.243.012.246.01.249.008.253.006.256.003.259.001.26-.001.257-.003.254-.006.25-.008.247-.01.244-.012.241-.015.237-.016.233-.018.231-.02.226-.022.224-.024.22-.025.216-.027.212-.029.21-.03.205-.032.202-.033.198-.035.194-.036.191-.037.187-.039.183-.039.179-.041.175-.042.172-.043.168-.044.163-.045.16-.045.155-.047.152-.047.148-.048.143-.048.139-.05.136-.049.131-.05.126-.051.123-.051.118-.051.114-.052.11-.052.106-.052.101-.052.096-.052.092-.052.088-.052.083-.052.079-.052.074-.051.07-.052.065-.051.06-.05.056-.051.051-.049.023-.025.023-.024.021-.025.02-.024.019-.024.018-.024.017-.024.015-.023.014-.023.013-.024.012-.022.01-.023.01-.023.008-.022.006-.022.006-.022.004-.021.004-.022.001-.021.001-.021v-4.139l-.077.054-.08.054-.083.054-.085.052-.087.053-.09.051-.093.051-.095.051-.097.05-.1.049-.102.049-.105.048-.106.047-.109.047-.111.046-.114.045-.115.044-.118.044-.12.044-.122.042-.124.042-.126.041-.128.04-.13.039-.132.039-.134.038-.135.037-.138.036-.139.036-.142.035-.143.033-.144.033-.147.033-.148.031-.15.03-.151.03-.153.028-.154.028-.156.027-.158.026-.159.025-.161.024-.162.023-.163.022-.165.021-.166.02-.167.019-.169.018-.169.017-.171.016-.173.015-.173.014-.175.013-.175.012-.177.011-.178.009-.179.009-.179.007-.181.007-.182.005-.182.004-.184.003-.184.002h-.37l-.184-.002-.184-.003-.182-.004-.182-.005-.181-.007-.179-.007-.179-.009-.178-.009-.176-.011-.176-.012-.175-.013-.173-.014-.172-.015-.171-.016-.17-.017-.169-.018-.167-.019-.166-.02-.165-.021-.163-.022-.162-.023-.161-.024-.159-.025-.157-.026-.156-.027-.155-.028-.153-.028-.151-.03-.15-.03-.148-.031-.146-.033-.145-.033-.143-.033-.141-.035-.14-.036-.137-.036-.136-.037-.134-.038-.132-.039-.13-.039-.128-.04-.126-.041-.124-.042-.122-.043-.12-.043-.117-.044-.116-.044-.113-.046-.112-.046-.109-.046-.106-.047-.105-.048-.102-.049-.1-.049-.097-.05-.095-.051-.093-.051-.09-.051-.087-.053-.085-.052-.083-.054-.08-.054-.077-.054v4.139zm0-5.666v.011l.001.02.003.022.004.021.005.022.006.021.007.022.009.023.01.022.011.023.012.023.013.023.015.023.016.024.017.024.018.023.019.024.021.025.022.024.023.024.024.025.052.05.056.05.061.05.066.051.07.051.075.052.079.051.084.052.088.052.092.052.097.052.102.052.105.051.11.052.114.051.119.051.123.051.127.05.131.05.135.05.139.049.144.048.147.048.152.047.155.046.16.045.163.045.167.043.171.043.176.042.178.04.183.04.187.038.19.037.194.036.197.034.202.033.204.032.209.03.212.028.216.027.219.025.222.024.226.021.23.02.233.018.236.017.24.014.243.012.246.01.249.008.253.006.256.003.259.001.26-.001.257-.003.254-.006.25-.008.247-.01.244-.013.241-.014.237-.016.233-.018.231-.02.226-.022.224-.024.22-.025.216-.027.212-.029.21-.03.205-.032.202-.033.198-.035.194-.036.191-.037.187-.039.183-.039.179-.041.175-.042.172-.043.168-.044.163-.045.16-.045.155-.047.152-.047.148-.048.143-.049.139-.049.136-.049.131-.051.126-.05.123-.051.118-.052.114-.051.11-.052.106-.052.101-.052.096-.052.092-.052.088-.052.083-.052.079-.052.074-.052.07-.051.065-.051.06-.051.056-.05.051-.049.023-.025.023-.025.021-.024.02-.024.019-.024.018-.024.017-.024.015-.023.014-.024.013-.023.012-.023.01-.022.01-.023.008-.022.006-.022.006-.022.004-.022.004-.021.001-.021.001-.021v-4.153l-.077.054-.08.054-.083.053-.085.053-.087.053-.09.051-.093.051-.095.051-.097.05-.1.049-.102.048-.105.048-.106.048-.109.046-.111.046-.114.046-.115.044-.118.044-.12.043-.122.043-.124.042-.126.041-.128.04-.13.039-.132.039-.134.038-.135.037-.138.036-.139.036-.142.034-.143.034-.144.033-.147.032-.148.032-.15.03-.151.03-.153.028-.154.028-.156.027-.158.026-.159.024-.161.024-.162.023-.163.023-.165.021-.166.02-.167.019-.169.018-.169.017-.171.016-.173.015-.173.014-.175.013-.175.012-.177.01-.178.01-.179.009-.179.007-.181.006-.182.006-.182.004-.184.003-.184.001-.185.001-.185-.001-.184-.001-.184-.003-.182-.004-.182-.006-.181-.006-.179-.007-.179-.009-.178-.01-.176-.01-.176-.012-.175-.013-.173-.014-.172-.015-.171-.016-.17-.017-.169-.018-.167-.019-.166-.02-.165-.021-.163-.023-.162-.023-.161-.024-.159-.024-.157-.026-.156-.027-.155-.028-.153-.028-.151-.03-.15-.03-.148-.032-.146-.032-.145-.033-.143-.034-.141-.034-.14-.036-.137-.036-.136-.037-.134-.038-.132-.039-.13-.039-.128-.041-.126-.041-.124-.041-.122-.043-.12-.043-.117-.044-.116-.044-.113-.046-.112-.046-.109-.046-.106-.048-.105-.048-.102-.048-.1-.05-.097-.049-.095-.051-.093-.051-.09-.052-.087-.052-.085-.053-.083-.053-.08-.054-.077-.054v4.153zm8.74-8.179l-.257.004-.254.005-.25.008-.247.011-.244.012-.241.014-.237.016-.233.018-.231.021-.226.022-.224.023-.22.026-.216.027-.212.028-.21.031-.205.032-.202.033-.198.034-.194.036-.191.038-.187.038-.183.04-.179.041-.175.042-.172.043-.168.043-.163.045-.16.046-.155.046-.152.048-.148.048-.143.048-.139.049-.136.05-.131.05-.126.051-.123.051-.118.051-.114.052-.11.052-.106.052-.101.052-.096.052-.092.052-.088.052-.083.052-.079.052-.074.051-.07.052-.065.051-.06.05-.056.05-.051.05-.023.025-.023.024-.021.024-.02.025-.019.024-.018.024-.017.023-.015.024-.014.023-.013.023-.012.023-.01.023-.01.022-.008.022-.006.023-.006.021-.004.022-.004.021-.001.021-.001.021.001.021.001.021.004.021.004.022.006.021.006.023.008.022.01.022.01.023.012.023.013.023.014.023.015.024.017.023.018.024.019.024.02.025.021.024.023.024.023.025.051.05.056.05.06.05.065.051.07.052.074.051.079.052.083.052.088.052.092.052.096.052.101.052.106.052.11.052.114.052.118.051.123.051.126.051.131.05.136.05.139.049.143.048.148.048.152.048.155.046.16.046.163.045.168.043.172.043.175.042.179.041.183.04.187.038.191.038.194.036.198.034.202.033.205.032.21.031.212.028.216.027.22.026.224.023.226.022.231.021.233.018.237.016.241.014.244.012.247.011.25.008.254.005.257.004.26.001.26-.001.257-.004.254-.005.25-.008.247-.011.244-.012.241-.014.237-.016.233-.018.231-.021.226-.022.224-.023.22-.026.216-.027.212-.028.21-.031.205-.032.202-.033.198-.034.194-.036.191-.038.187-.038.183-.04.179-.041.175-.042.172-.043.168-.043.163-.045.16-.046.155-.046.152-.048.148-.048.143-.048.139-.049.136-.05.131-.05.126-.051.123-.051.118-.051.114-.052.11-.052.106-.052.101-.052.096-.052.092-.052.088-.052.083-.052.079-.052.074-.051.07-.052.065-.051.06-.05.056-.05.051-.05.023-.025.023-.024.021-.024.02-.025.019-.024.018-.024.017-.023.015-.024.014-.023.013-.023.012-.023.01-.023.01-.022.008-.022.006-.023.006-.021.004-.022.004-.021.001-.021.001-.021-.001-.021-.001-.021-.004-.021-.004-.022-.006-.021-.006-.023-.008-.022-.01-.022-.01-.023-.012-.023-.013-.023-.014-.023-.015-.024-.017-.023-.018-.024-.019-.024-.02-.025-.021-.024-.023-.024-.023-.025-.051-.05-.056-.05-.06-.05-.065-.051-.07-.052-.074-.051-.079-.052-.083-.052-.088-.052-.092-.052-.096-.052-.101-.052-.106-.052-.11-.052-.114-.052-.118-.051-.123-.051-.126-.051-.131-.05-.136-.05-.139-.049-.143-.048-.148-.048-.152-.048-.155-.046-.16-.046-.163-.045-.168-.043-.172-.043-.175-.042-.179-.041-.183-.04-.187-.038-.191-.038-.194-.036-.198-.034-.202-.033-.205-.032-.21-.031-.212-.028-.216-.027-.22-.026-.224-.023-.226-.022-.231-.021-.233-.018-.237-.016-.241-.014-.244-.012-.247-.011-.25-.008-.254-.005-.257-.004-.26-.001-.26.001z'/%3e%3c/symbol%3e%3c/defs%3e%3cdefs%3e%3csymbol%20id='clock'%20width='24'%20height='24'%3e%3cpath%20transform='scale(.5)'%20d='M12%202c5.514%200%2010%204.486%2010%2010s-4.486%2010-10%2010-10-4.486-10-10%204.486-10%2010-10zm0-2c-6.627%200-12%205.373-12%2012s5.373%2012%2012%2012%2012-5.373%2012-12-5.373-12-12-12zm5.848%2012.459c.202.038.202.333.001.372-1.907.361-6.045%201.111-6.547%201.111-.719%200-1.301-.582-1.301-1.301%200-.512.77-5.447%201.125-7.445.034-.192.312-.181.343.014l.985%206.238%205.394%201.011z'/%3e%3c/symbol%3e%3c/defs%3e%3cdefs%3e%3cmarker%20id='arrowhead'%20refX='7.9'%20refY='5'%20markerUnits='userSpaceOnUse'%20markerWidth='12'%20markerHeight='12'%20orient='auto-start-reverse'%3e%3cpath%20d='M%20-1%200%20L%2010%205%20L%200%2010%20z'/%3e%3c/marker%3e%3c/defs%3e%3cdefs%3e%3cmarker%20id='crosshead'%20markerWidth='15'%20markerHeight='8'%20orient='auto'%20refX='4'%20refY='4.5'%3e%3cpath%20fill='none'%20stroke='black'%20stroke-width='1pt'%20d='M%201%2c2%20L%206%2c7%20M%206%2c2%20L%201%2c7'%20style='stroke-dasharray:%200%2c%200%3b'/%3e%3c/marker%3e%3c/defs%3e%3cdefs%3e%3cmarker%20id='filled-head'%20refX='15.5'%20refY='7'%20markerWidth='20'%20markerHeight='28'%20orient='auto'%3e%3cpath%20d='M%2018%2c7%20L9%2c13%20L14%2c7%20L9%2c1%20Z'/%3e%3c/marker%3e%3c/defs%3e%3cdefs%3e%3cmarker%20id='sequencenumber'%20refX='15'%20refY='15'%20markerWidth='60'%20markerHeight='40'%20orient='auto'%3e%3ccircle%20cx='15'%20cy='15'%20r='6'/%3e%3c/marker%3e%3c/defs%3e%3cg%3e%3crect%20x='601.5'%20y='146'%20fill='%23EDF2AE'%20stroke='%23666'%20width='300'%20height='37'%20class='note'/%3e%3ctext%20x='752'%20y='151'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='noteText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3e%3ctspan%20x='752'%3eGPUs:%20SGLang%20servers.%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect%20x='331.5'%20y='213'%20fill='%23EDF2AE'%20stroke='%23666'%20width='335'%20height='37'%20class='note'/%3e%3ctext%20x='499'%20y='218'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='noteText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3e%3ctspan%20x='499'%3e1.%20Document%20Parsing%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect%20x='331.5'%20y='378'%20fill='%23EDF2AE'%20stroke='%23666'%20width='570'%20height='37'%20class='note'/%3e%3ctext%20x='617'%20y='383'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='noteText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3e%3ctspan%20x='617'%3e2.%20Problem%20Splitting%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect%20x='331.5'%20y='543'%20fill='%23EDF2AE'%20stroke='%23666'%20width='1060'%20height='37'%20class='note'/%3e%3ctext%20x='862'%20y='548'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='noteText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3e%3ctspan%20x='862'%3e3.%20Solving%20Loop%20(per%20question)%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3cline%20x1='353'%20y1='590'%20x2='1370'%20y2='590'%20class='loopLine'/%3e%3cline%20x1='1370'%20y1='590'%20x2='1370'%20y2='987'%20class='loopLine'/%3e%3cline%20x1='353'%20y1='987'%20x2='1370'%20y2='987'%20class='loopLine'/%3e%3cline%20x1='353'%20y1='590'%20x2='353'%20y2='987'%20class='loopLine'/%3e%3cpolygon%20points='353%2c590%20403%2c590%20403%2c603%20394.6%2c610%20353%2c610'%20class='labelBox'/%3e%3ctext%20x='378'%20y='603'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='labelText'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eloop%3c/text%3e%3ctext%20x='886.5'%20y='608'%20text-anchor='middle'%20class='loopText'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3e%3ctspan%20x='886.5'%3e%5beach%20step%20until%20answer%20or%20max%20steps%5d%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect%20x='52.5'%20y='1027'%20fill='%23EDF2AE'%20stroke='%23666'%20width='344'%20height='37'%20class='note'/%3e%3ctext%20x='225'%20y='1032'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='noteText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3e%3ctspan%20x='225'%3e4.%20Compile%20answer%20to%20PDF%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%20class='actor-man%20actor-top'%20name='U'%3e%3cline%20id='actor-man-torso0'%20x1='85'%20y1='52'%20x2='85'%20y2='72'/%3e%3cline%20id='actor-man-arms0'%20x1='67'%20y1='60'%20x2='103'%20y2='60'/%3e%3cline%20x1='67'%20y1='87'%20x2='85'%20y2='72'/%3e%3cline%20x1='85'%20y1='72'%20x2='101'%20y2='87'/%3e%3ccircle%20cx='85'%20cy='37'%20r='15'%20width='170'%20height='65'/%3e%3ctext%20x='85'%20y='94.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-man'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='85'%20dy='0'%3eUser%3c/tspan%3e%3c/text%3e%3c/g%3e%3ctext%20x='223'%20y='107'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eInput%20problems%20(PDF)%3c/text%3e%3cline%20x1='86'%20y1='136'%20x2='360'%20y2='136'%20class='messageLine0'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='fill:%20none%3b'/%3e%3ctext%20x='498'%20y='265'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eUpload%20PDF%3c/text%3e%3cline%20x1='365'%20y1='294'%20x2='630'%20y2='294'%20class='messageLine0'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='fill:%20none%3b'/%3e%3ctext%20x='501'%20y='309'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eMarkdown%20(text%20%2b%20images)%3c/text%3e%3cline%20x1='633'%20y1='338'%20x2='368'%20y2='338'%20class='messageLine1'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='stroke-dasharray:%203%2c%203%3b%20fill:%20none%3b'/%3e%3ctext%20x='615'%20y='430'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eRequest%20question%20boundaries%3c/text%3e%3cline%20x1='365'%20y1='459'%20x2='865'%20y2='459'%20class='messageLine0'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='fill:%20none%3b'/%3e%3ctext%20x='618'%20y='474'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eSplit%20into%20Q1%2c%20Q2%2c%20...%3c/text%3e%3cline%20x1='868'%20y1='503'%20x2='368'%20y2='503'%20class='messageLine1'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='stroke-dasharray:%203%2c%203%3b%20fill:%20none%3b'/%3e%3ctext%20x='615'%20y='640'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eSpawn%20N%20parallel%20branches%20(reason%20%2b%20pick%20tools)%3c/text%3e%3cline%20x1='365'%20y1='669'%20x2='865'%20y2='669'%20class='messageLine0'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='fill:%20none%3b'/%3e%3ctext%20x='743'%20y='684'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eCreate%20a%20sandbox%20per%20branch%3c/text%3e%3cline%20x1='365'%20y1='713'%20x2='1120'%20y2='713'%20class='messageLine0'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='fill:%20none%3b'/%3e%3ctext%20x='618'%20y='728'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eTool%20calls%3c/text%3e%3cline%20x1='868'%20y1='757'%20x2='368'%20y2='757'%20class='messageLine1'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='stroke-dasharray:%203%2c%203%3b%20fill:%20none%3b'/%3e%3ctext%20x='860'%20y='772'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eExecute%20Science%20tools%3c/text%3e%3cline%20x1='365'%20y1='801'%20x2='1355'%20y2='801'%20class='messageLine0'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='fill:%20none%3b'/%3e%3ctext%20x='863'%20y='816'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eExecution%20output%3c/text%3e%3cline%20x1='1358'%20y1='845'%20x2='368'%20y2='845'%20class='messageLine1'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='stroke-dasharray:%203%2c%203%3b%20fill:%20none%3b'/%3e%3ctext%20x='618'%20y='860'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eCandidate%20solutions%20(peer-reviewed)%3c/text%3e%3cline%20x1='868'%20y1='889'%20x2='368'%20y2='889'%20class='messageLine1'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='stroke-dasharray:%203%2c%203%3b%20fill:%20none%3b'/%3e%3ctext%20x='615'%20y='904'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eCritic%20ranks%20branches%3c/text%3e%3cline%20x1='365'%20y1='933'%20x2='865'%20y2='933'%20class='messageLine0'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='fill:%20none%3b'/%3e%3ctext%20x='618'%20y='948'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eBest%20Solution%3c/text%3e%3cline%20x1='868'%20y1='977'%20x2='368'%20y2='977'%20class='messageLine1'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='stroke-dasharray:%203%2c%203%3b%20fill:%20none%3b'/%3e%3ctext%20x='226'%20y='1079'%20text-anchor='middle'%20dominant-baseline='middle'%20alignment-baseline='middle'%20class='messageText'%20dy='1em'%20style='font-family:%20arial%2c%20sans-serif%3b%20font-size:%2016px%3b%20font-weight:%20400%3b'%3eOutput%20final%20solution%20(PDF)%3c/text%3e%3cline%20x1='363'%20y1='1108'%20x2='89'%20y2='1108'%20class='messageLine1'%20stroke-width='2'%20stroke='none'%20marker-end='url(%23arrowhead)'%20style='stroke-dasharray:%203%2c%203%3b%20fill:%20none%3b'/%3e%3cg%20class='actor-man%20actor-bottom'%20name='U'%3e%3cline%20id='actor-man-torso5'%20x1='85'%20y1='1163'%20x2='85'%20y2='1183'/%3e%3cline%20id='actor-man-arms5'%20x1='67'%20y1='1171'%20x2='103'%20y2='1171'/%3e%3cline%20x1='67'%20y1='1198'%20x2='85'%20y2='1183'/%3e%3cline%20x1='85'%20y1='1183'%20x2='101'%20y2='1198'/%3e%3ccircle%20cx='85'%20cy='1148'%20r='15'%20width='170'%20height='65'/%3e%3ctext%20x='85'%20y='1205.5'%20dominant-baseline='central'%20alignment-baseline='central'%20class='actor%20actor-man'%20style='text-anchor:%20middle%3b%20font-size:%2016px%3b%20font-weight:%20400%3b%20font-family:%20arial%2c%20sans-serif%3b'%3e%3ctspan%20x='85'%20dy='0'%3eUser%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/svg%3e)
' stroke='rgb(0%2c0%2c0%2c 0.5)' width='455' height='1228' class='rect'/%3e%3ctext x='1241.5' y='13.5' dominant-baseline='central' alignment-baseline='central' class='text' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='1241.5' dy='0'%3eSandbox%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect x='254' y='-5' fill='rgba(92%2c 88%2c 39%2c 0.18)' stroke='rgb(0%2c0%2c0%2c 0.5)' width='725' height='1228' class='rect'/%3e%3ctext x='616.5' y='13.5' dominant-baseline='central' alignment-baseline='central' class='text' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='616.5' dy='0'%3eGPU Node%3c/tspan%3e%3c/text%3e%3c/g%3e%3crect x='42.5' y='1007' fill='rgba(94%2c 87%2c 150%2c 0.14)' width='364' height='111' class='rect'/%3e%3crect x='321.5' y='523' fill='rgba(164%2c 68%2c 68%2c 0.14)' width='1080' height='474' class='rect'/%3e%3crect x='321.5' y='358' fill='rgba(44%2c 130%2c 86%2c 0.14)' width='590' height='155' class='rect'/%3e%3crect x='321.5' y='193' fill='rgba(173%2c 116%2c 43%2c 0.14)' width='355' height='155' class='rect'/%3e%3cg%3e%3crect x='1274' y='1138' fill='%23eaeaea' stroke='%23666' width='170' height='65' name='T' rx='3' ry='3' class='actor actor-bottom'/%3e%3ctext x='1359' y='1170.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-box' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='1359' dy='0'%3eScience Tools%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect x='1039' y='1138' fill='%23eaeaea' stroke='%23666' width='170' height='65' name='S' rx='3' ry='3' class='actor actor-bottom'/%3e%3ctext x='1124' y='1170.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-box' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='1124' dy='0'%3eSandbox API%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect x='784' y='1138' fill='%23eaeaea' stroke='%23666' width='170' height='65' name='G' rx='3' ry='3' class='actor actor-bottom'/%3e%3ctext x='869' y='1170.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-box' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='869' dy='0'%3eSGLang servers%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect x='549' y='1138' fill='%23eaeaea' stroke='%23666' width='170' height='65' name='O' rx='3' ry='3' class='actor actor-bottom'/%3e%3ctext x='634' y='1170.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-box' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='634' dy='0'%3eOCR server%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect x='279' y='1138' fill='%23eaeaea' stroke='%23666' width='170' height='65' name='A' rx='3' ry='3' class='actor actor-bottom'/%3e%3ctext x='364' y='1170.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-box' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='364' dy='0'%3eAgent Core (Rust)%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg/%3e%3cg%3e%3cline id='actor5' x1='1359' y1='92' x2='1359' y2='1138' class='actor-line 200' stroke-width='0.5px' stroke='%23999' name='T'/%3e%3cg id='root-5'%3e%3crect x='1274' y='27' fill='%23eaeaea' stroke='%23666' width='170' height='65' name='T' rx='3' ry='3' class='actor actor-top'/%3e%3ctext x='1359' y='59.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-box' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='1359' dy='0'%3eScience Tools%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/g%3e%3cg%3e%3cline id='actor4' x1='1124' y1='92' x2='1124' y2='1138' class='actor-line 200' stroke-width='0.5px' stroke='%23999' name='S'/%3e%3cg id='root-4'%3e%3crect x='1039' y='27' fill='%23eaeaea' stroke='%23666' width='170' height='65' name='S' rx='3' ry='3' class='actor actor-top'/%3e%3ctext x='1124' y='59.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-box' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='1124' dy='0'%3eSandbox API%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/g%3e%3cg%3e%3cline id='actor3' x1='869' y1='92' x2='869' y2='1138' class='actor-line 200' stroke-width='0.5px' stroke='%23999' name='G'/%3e%3cg id='root-3'%3e%3crect x='784' y='27' fill='%23eaeaea' stroke='%23666' width='170' height='65' name='G' rx='3' ry='3' class='actor actor-top'/%3e%3ctext x='869' y='59.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-box' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='869' dy='0'%3eSGLang servers%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/g%3e%3cg%3e%3cline id='actor2' x1='634' y1='92' x2='634' y2='1138' class='actor-line 200' stroke-width='0.5px' stroke='%23999' name='O'/%3e%3cg id='root-2'%3e%3crect x='549' y='27' fill='%23eaeaea' stroke='%23666' width='170' height='65' name='O' rx='3' ry='3' class='actor actor-top'/%3e%3ctext x='634' y='59.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-box' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='634' dy='0'%3eOCR server%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/g%3e%3cg%3e%3cline id='actor1' x1='364' y1='92' x2='364' y2='1138' class='actor-line 200' stroke-width='0.5px' stroke='%23999' name='A'/%3e%3cg id='root-1'%3e%3crect x='279' y='27' fill='%23eaeaea' stroke='%23666' width='170' height='65' name='A' rx='3' ry='3' class='actor actor-top'/%3e%3ctext x='364' y='59.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-box' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='364' dy='0'%3eAgent Core (Rust)%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/g%3e%3cg%3e%3cline id='actor0' x1='85' y1='107' x2='85' y2='1138' class='actor-line 200' stroke-width='0.5px' stroke='%23999' name='U'/%3e%3c/g%3e%3cstyle%3e%23mermaid-0%7bfont-family:arial%2csans-serif%3bfont-size:16px%3bfill:black%3b%7d%40keyframes edge-animation-frame%7bfrom%7bstroke-dashoffset:0%3b%7d%7d%40keyframes dash%7bto%7bstroke-dashoffset:0%3b%7d%7d%23mermaid-0 .edge-animation-slow%7bstroke-dasharray:9%2c5!important%3bstroke-dashoffset:900%3banimation:dash 50s linear infinite%3bstroke-linecap:round%3b%7d%23mermaid-0 .edge-animation-fast%7bstroke-dasharray:9%2c5!important%3bstroke-dashoffset:900%3banimation:dash 20s linear infinite%3bstroke-linecap:round%3b%7d%23mermaid-0 .error-icon%7bfill:%23552222%3b%7d%23mermaid-0 .error-text%7bfill:%23552222%3bstroke:%23552222%3b%7d%23mermaid-0 .edge-thickness-normal%7bstroke-width:1px%3b%7d%23mermaid-0 .edge-thickness-thick%7bstroke-width:3.5px%3b%7d%23mermaid-0 .edge-pattern-solid%7bstroke-dasharray:0%3b%7d%23mermaid-0 .edge-thickness-invisible%7bstroke-width:0%3bfill:none%3b%7d%23mermaid-0 .edge-pattern-dashed%7bstroke-dasharray:3%3b%7d%23mermaid-0 .edge-pattern-dotted%7bstroke-dasharray:2%3b%7d%23mermaid-0 .marker%7bfill:%23666%3bstroke:%23666%3b%7d%23mermaid-0 .marker.cross%7bstroke:%23666%3b%7d%23mermaid-0 svg%7bfont-family:arial%2csans-serif%3bfont-size:16px%3b%7d%23mermaid-0 p%7bmargin:0%3b%7d%23mermaid-0 .actor%7bstroke:hsl(0%2c 0%25%2c 83%25)%3bfill:%23eee%3b%7d%23mermaid-0 text.actor%26gt%3btspan%7bfill:%23333%3bstroke:none%3b%7d%23mermaid-0 .actor-line%7bstroke:%236b7280%3b%7d%23mermaid-0 .innerArc%7bstroke-width:1.5%3bstroke-dasharray:none%3b%7d%23mermaid-0 .messageLine0%7bstroke-width:1.5%3bstroke-dasharray:none%3bstroke:%23333%3b%7d%23mermaid-0 .messageLine1%7bstroke-width:1.5%3bstroke-dasharray:2%2c2%3bstroke:%23333%3b%7d%23mermaid-0 %23arrowhead path%7bfill:%23333%3bstroke:%23333%3b%7d%23mermaid-0 .sequenceNumber%7bfill:white%3b%7d%23mermaid-0 %23sequencenumber%7bfill:%23333%3b%7d%23mermaid-0 %23crosshead path%7bfill:%23333%3bstroke:%23333%3b%7d%23mermaid-0 .messageText%7bfill:%23333%3bstroke:none%3b%7d%23mermaid-0 .labelBox%7bstroke:%234b5563%3bfill:%23eee%3b%7d%23mermaid-0 .labelText%2c%23mermaid-0 .labelText%26gt%3btspan%7bfill:%23333%3bstroke:none%3b%7d%23mermaid-0 .loopText%2c%23mermaid-0 .loopText%26gt%3btspan%7bfill:%23333%3bstroke:none%3b%7d%23mermaid-0 .loopLine%7bstroke-width:2px%3bstroke-dasharray:2%2c2%3bstroke:%234b5563%3bfill:%234b5563%3b%7d%23mermaid-0 .note%7bstroke:%23999%3bfill:%23666%3b%7d%23mermaid-0 .noteText%2c%23mermaid-0 .noteText%26gt%3btspan%7bfill:white%3bstroke:none%3b%7d%23mermaid-0 .activation0%7bfill:%23f4f4f4%3bstroke:%23666%3b%7d%23mermaid-0 .activation1%7bfill:%23f4f4f4%3bstroke:%23666%3b%7d%23mermaid-0 .activation2%7bfill:%23f4f4f4%3bstroke:%23666%3b%7d%23mermaid-0 .actorPopupMenu%7bposition:absolute%3b%7d%23mermaid-0 .actorPopupMenuPanel%7bposition:absolute%3bfill:%23eee%3bbox-shadow:0px 8px 16px 0px rgba(0%2c0%2c0%2c0.2)%3bfilter:drop-shadow(3px 5px 2px rgb(0 0 0 / 0.4))%3b%7d%23mermaid-0 .actor-man line%7bstroke:hsl(0%2c 0%25%2c 83%25)%3bfill:%23eee%3b%7d%23mermaid-0 .actor-man circle%2c%23mermaid-0 line%7bstroke:hsl(0%2c 0%25%2c 83%25)%3bfill:%23eee%3bstroke-width:2px%3b%7d%23mermaid-0 :root%7b--mermaid-font-family:arial%2csans-serif%3b%7d%3c/style%3e%3cg/%3e%3cdefs%3e%3csymbol id='computer' width='24' height='24'%3e%3cpath transform='scale(.5)' d='M2 2v13h20v-13h-20zm18 11h-16v-9h16v9zm-10.228 6l.466-1h3.524l.467 1h-4.457zm14.228 3h-24l2-6h2.104l-1.33 4h18.45l-1.297-4h2.073l2 6zm-5-10h-14v-7h14v7z'/%3e%3c/symbol%3e%3c/defs%3e%3cdefs%3e%3csymbol id='database' fill-rule='evenodd' clip-rule='evenodd'%3e%3cpath transform='scale(.5)' d='M12.258.001l.256.004.255.005.253.008.251.01.249.012.247.015.246.016.242.019.241.02.239.023.236.024.233.027.231.028.229.031.225.032.223.034.22.036.217.038.214.04.211.041.208.043.205.045.201.046.198.048.194.05.191.051.187.053.183.054.18.056.175.057.172.059.168.06.163.061.16.063.155.064.15.066.074.033.073.033.071.034.07.034.069.035.068.035.067.035.066.035.064.036.064.036.062.036.06.036.06.037.058.037.058.037.055.038.055.038.053.038.052.038.051.039.05.039.048.039.047.039.045.04.044.04.043.04.041.04.04.041.039.041.037.041.036.041.034.041.033.042.032.042.03.042.029.042.027.042.026.043.024.043.023.043.021.043.02.043.018.044.017.043.015.044.013.044.012.044.011.045.009.044.007.045.006.045.004.045.002.045.001.045v17l-.001.045-.002.045-.004.045-.006.045-.007.045-.009.044-.011.045-.012.044-.013.044-.015.044-.017.043-.018.044-.02.043-.021.043-.023.043-.024.043-.026.043-.027.042-.029.042-.03.042-.032.042-.033.042-.034.041-.036.041-.037.041-.039.041-.04.041-.041.04-.043.04-.044.04-.045.04-.047.039-.048.039-.05.039-.051.039-.052.038-.053.038-.055.038-.055.038-.058.037-.058.037-.06.037-.06.036-.062.036-.064.036-.064.036-.066.035-.067.035-.068.035-.069.035-.07.034-.071.034-.073.033-.074.033-.15.066-.155.064-.16.063-.163.061-.168.06-.172.059-.175.057-.18.056-.183.054-.187.053-.191.051-.194.05-.198.048-.201.046-.205.045-.208.043-.211.041-.214.04-.217.038-.22.036-.223.034-.225.032-.229.031-.231.028-.233.027-.236.024-.239.023-.241.02-.242.019-.246.016-.247.015-.249.012-.251.01-.253.008-.255.005-.256.004-.258.001-.258-.001-.256-.004-.255-.005-.253-.008-.251-.01-.249-.012-.247-.015-.245-.016-.243-.019-.241-.02-.238-.023-.236-.024-.234-.027-.231-.028-.228-.031-.226-.032-.223-.034-.22-.036-.217-.038-.214-.04-.211-.041-.208-.043-.204-.045-.201-.046-.198-.048-.195-.05-.19-.051-.187-.053-.184-.054-.179-.056-.176-.057-.172-.059-.167-.06-.164-.061-.159-.063-.155-.064-.151-.066-.074-.033-.072-.033-.072-.034-.07-.034-.069-.035-.068-.035-.067-.035-.066-.035-.064-.036-.063-.036-.062-.036-.061-.036-.06-.037-.058-.037-.057-.037-.056-.038-.055-.038-.053-.038-.052-.038-.051-.039-.049-.039-.049-.039-.046-.039-.046-.04-.044-.04-.043-.04-.041-.04-.04-.041-.039-.041-.037-.041-.036-.041-.034-.041-.033-.042-.032-.042-.03-.042-.029-.042-.027-.042-.026-.043-.024-.043-.023-.043-.021-.043-.02-.043-.018-.044-.017-.043-.015-.044-.013-.044-.012-.044-.011-.045-.009-.044-.007-.045-.006-.045-.004-.045-.002-.045-.001-.045v-17l.001-.045.002-.045.004-.045.006-.045.007-.045.009-.044.011-.045.012-.044.013-.044.015-.044.017-.043.018-.044.02-.043.021-.043.023-.043.024-.043.026-.043.027-.042.029-.042.03-.042.032-.042.033-.042.034-.041.036-.041.037-.041.039-.041.04-.041.041-.04.043-.04.044-.04.046-.04.046-.039.049-.039.049-.039.051-.039.052-.038.053-.038.055-.038.056-.038.057-.037.058-.037.06-.037.061-.036.062-.036.063-.036.064-.036.066-.035.067-.035.068-.035.069-.035.07-.034.072-.034.072-.033.074-.033.151-.066.155-.064.159-.063.164-.061.167-.06.172-.059.176-.057.179-.056.184-.054.187-.053.19-.051.195-.05.198-.048.201-.046.204-.045.208-.043.211-.041.214-.04.217-.038.22-.036.223-.034.226-.032.228-.031.231-.028.234-.027.236-.024.238-.023.241-.02.243-.019.245-.016.247-.015.249-.012.251-.01.253-.008.255-.005.256-.004.258-.001.258.001zm-9.258 20.499v.01l.001.021.003.021.004.022.005.021.006.022.007.022.009.023.01.022.011.023.012.023.013.023.015.023.016.024.017.023.018.024.019.024.021.024.022.025.023.024.024.025.052.049.056.05.061.051.066.051.07.051.075.051.079.052.084.052.088.052.092.052.097.052.102.051.105.052.11.052.114.051.119.051.123.051.127.05.131.05.135.05.139.048.144.049.147.047.152.047.155.047.16.045.163.045.167.043.171.043.176.041.178.041.183.039.187.039.19.037.194.035.197.035.202.033.204.031.209.03.212.029.216.027.219.025.222.024.226.021.23.02.233.018.236.016.24.015.243.012.246.01.249.008.253.005.256.004.259.001.26-.001.257-.004.254-.005.25-.008.247-.011.244-.012.241-.014.237-.016.233-.018.231-.021.226-.021.224-.024.22-.026.216-.027.212-.028.21-.031.205-.031.202-.034.198-.034.194-.036.191-.037.187-.039.183-.04.179-.04.175-.042.172-.043.168-.044.163-.045.16-.046.155-.046.152-.047.148-.048.143-.049.139-.049.136-.05.131-.05.126-.05.123-.051.118-.052.114-.051.11-.052.106-.052.101-.052.096-.052.092-.052.088-.053.083-.051.079-.052.074-.052.07-.051.065-.051.06-.051.056-.05.051-.05.023-.024.023-.025.021-.024.02-.024.019-.024.018-.024.017-.024.015-.023.014-.024.013-.023.012-.023.01-.023.01-.022.008-.022.006-.022.006-.022.004-.022.004-.021.001-.021.001-.021v-4.127l-.077.055-.08.053-.083.054-.085.053-.087.052-.09.052-.093.051-.095.05-.097.05-.1.049-.102.049-.105.048-.106.047-.109.047-.111.046-.114.045-.115.045-.118.044-.12.043-.122.042-.124.042-.126.041-.128.04-.13.04-.132.038-.134.038-.135.037-.138.037-.139.035-.142.035-.143.034-.144.033-.147.032-.148.031-.15.03-.151.03-.153.029-.154.027-.156.027-.158.026-.159.025-.161.024-.162.023-.163.022-.165.021-.166.02-.167.019-.169.018-.169.017-.171.016-.173.015-.173.014-.175.013-.175.012-.177.011-.178.01-.179.008-.179.008-.181.006-.182.005-.182.004-.184.003-.184.002h-.37l-.184-.002-.184-.003-.182-.004-.182-.005-.181-.006-.179-.008-.179-.008-.178-.01-.176-.011-.176-.012-.175-.013-.173-.014-.172-.015-.171-.016-.17-.017-.169-.018-.167-.019-.166-.02-.165-.021-.163-.022-.162-.023-.161-.024-.159-.025-.157-.026-.156-.027-.155-.027-.153-.029-.151-.03-.15-.03-.148-.031-.146-.032-.145-.033-.143-.034-.141-.035-.14-.035-.137-.037-.136-.037-.134-.038-.132-.038-.13-.04-.128-.04-.126-.041-.124-.042-.122-.042-.12-.044-.117-.043-.116-.045-.113-.045-.112-.046-.109-.047-.106-.047-.105-.048-.102-.049-.1-.049-.097-.05-.095-.05-.093-.052-.09-.051-.087-.052-.085-.053-.083-.054-.08-.054-.077-.054v4.127zm0-5.654v.011l.001.021.003.021.004.021.005.022.006.022.007.022.009.022.01.022.011.023.012.023.013.023.015.024.016.023.017.024.018.024.019.024.021.024.022.024.023.025.024.024.052.05.056.05.061.05.066.051.07.051.075.052.079.051.084.052.088.052.092.052.097.052.102.052.105.052.11.051.114.051.119.052.123.05.127.051.131.05.135.049.139.049.144.048.147.048.152.047.155.046.16.045.163.045.167.044.171.042.176.042.178.04.183.04.187.038.19.037.194.036.197.034.202.033.204.032.209.03.212.028.216.027.219.025.222.024.226.022.23.02.233.018.236.016.24.014.243.012.246.01.249.008.253.006.256.003.259.001.26-.001.257-.003.254-.006.25-.008.247-.01.244-.012.241-.015.237-.016.233-.018.231-.02.226-.022.224-.024.22-.025.216-.027.212-.029.21-.03.205-.032.202-.033.198-.035.194-.036.191-.037.187-.039.183-.039.179-.041.175-.042.172-.043.168-.044.163-.045.16-.045.155-.047.152-.047.148-.048.143-.048.139-.05.136-.049.131-.05.126-.051.123-.051.118-.051.114-.052.11-.052.106-.052.101-.052.096-.052.092-.052.088-.052.083-.052.079-.052.074-.051.07-.052.065-.051.06-.05.056-.051.051-.049.023-.025.023-.024.021-.025.02-.024.019-.024.018-.024.017-.024.015-.023.014-.023.013-.024.012-.022.01-.023.01-.023.008-.022.006-.022.006-.022.004-.021.004-.022.001-.021.001-.021v-4.139l-.077.054-.08.054-.083.054-.085.052-.087.053-.09.051-.093.051-.095.051-.097.05-.1.049-.102.049-.105.048-.106.047-.109.047-.111.046-.114.045-.115.044-.118.044-.12.044-.122.042-.124.042-.126.041-.128.04-.13.039-.132.039-.134.038-.135.037-.138.036-.139.036-.142.035-.143.033-.144.033-.147.033-.148.031-.15.03-.151.03-.153.028-.154.028-.156.027-.158.026-.159.025-.161.024-.162.023-.163.022-.165.021-.166.02-.167.019-.169.018-.169.017-.171.016-.173.015-.173.014-.175.013-.175.012-.177.011-.178.009-.179.009-.179.007-.181.007-.182.005-.182.004-.184.003-.184.002h-.37l-.184-.002-.184-.003-.182-.004-.182-.005-.181-.007-.179-.007-.179-.009-.178-.009-.176-.011-.176-.012-.175-.013-.173-.014-.172-.015-.171-.016-.17-.017-.169-.018-.167-.019-.166-.02-.165-.021-.163-.022-.162-.023-.161-.024-.159-.025-.157-.026-.156-.027-.155-.028-.153-.028-.151-.03-.15-.03-.148-.031-.146-.033-.145-.033-.143-.033-.141-.035-.14-.036-.137-.036-.136-.037-.134-.038-.132-.039-.13-.039-.128-.04-.126-.041-.124-.042-.122-.043-.12-.043-.117-.044-.116-.044-.113-.046-.112-.046-.109-.046-.106-.047-.105-.048-.102-.049-.1-.049-.097-.05-.095-.051-.093-.051-.09-.051-.087-.053-.085-.052-.083-.054-.08-.054-.077-.054v4.139zm0-5.666v.011l.001.02.003.022.004.021.005.022.006.021.007.022.009.023.01.022.011.023.012.023.013.023.015.023.016.024.017.024.018.023.019.024.021.025.022.024.023.024.024.025.052.05.056.05.061.05.066.051.07.051.075.052.079.051.084.052.088.052.092.052.097.052.102.052.105.051.11.052.114.051.119.051.123.051.127.05.131.05.135.05.139.049.144.048.147.048.152.047.155.046.16.045.163.045.167.043.171.043.176.042.178.04.183.04.187.038.19.037.194.036.197.034.202.033.204.032.209.03.212.028.216.027.219.025.222.024.226.021.23.02.233.018.236.017.24.014.243.012.246.01.249.008.253.006.256.003.259.001.26-.001.257-.003.254-.006.25-.008.247-.01.244-.013.241-.014.237-.016.233-.018.231-.02.226-.022.224-.024.22-.025.216-.027.212-.029.21-.03.205-.032.202-.033.198-.035.194-.036.191-.037.187-.039.183-.039.179-.041.175-.042.172-.043.168-.044.163-.045.16-.045.155-.047.152-.047.148-.048.143-.049.139-.049.136-.049.131-.051.126-.05.123-.051.118-.052.114-.051.11-.052.106-.052.101-.052.096-.052.092-.052.088-.052.083-.052.079-.052.074-.052.07-.051.065-.051.06-.051.056-.05.051-.049.023-.025.023-.025.021-.024.02-.024.019-.024.018-.024.017-.024.015-.023.014-.024.013-.023.012-.023.01-.022.01-.023.008-.022.006-.022.006-.022.004-.022.004-.021.001-.021.001-.021v-4.153l-.077.054-.08.054-.083.053-.085.053-.087.053-.09.051-.093.051-.095.051-.097.05-.1.049-.102.048-.105.048-.106.048-.109.046-.111.046-.114.046-.115.044-.118.044-.12.043-.122.043-.124.042-.126.041-.128.04-.13.039-.132.039-.134.038-.135.037-.138.036-.139.036-.142.034-.143.034-.144.033-.147.032-.148.032-.15.03-.151.03-.153.028-.154.028-.156.027-.158.026-.159.024-.161.024-.162.023-.163.023-.165.021-.166.02-.167.019-.169.018-.169.017-.171.016-.173.015-.173.014-.175.013-.175.012-.177.01-.178.01-.179.009-.179.007-.181.006-.182.006-.182.004-.184.003-.184.001-.185.001-.185-.001-.184-.001-.184-.003-.182-.004-.182-.006-.181-.006-.179-.007-.179-.009-.178-.01-.176-.01-.176-.012-.175-.013-.173-.014-.172-.015-.171-.016-.17-.017-.169-.018-.167-.019-.166-.02-.165-.021-.163-.023-.162-.023-.161-.024-.159-.024-.157-.026-.156-.027-.155-.028-.153-.028-.151-.03-.15-.03-.148-.032-.146-.032-.145-.033-.143-.034-.141-.034-.14-.036-.137-.036-.136-.037-.134-.038-.132-.039-.13-.039-.128-.041-.126-.041-.124-.041-.122-.043-.12-.043-.117-.044-.116-.044-.113-.046-.112-.046-.109-.046-.106-.048-.105-.048-.102-.048-.1-.05-.097-.049-.095-.051-.093-.051-.09-.052-.087-.052-.085-.053-.083-.053-.08-.054-.077-.054v4.153zm8.74-8.179l-.257.004-.254.005-.25.008-.247.011-.244.012-.241.014-.237.016-.233.018-.231.021-.226.022-.224.023-.22.026-.216.027-.212.028-.21.031-.205.032-.202.033-.198.034-.194.036-.191.038-.187.038-.183.04-.179.041-.175.042-.172.043-.168.043-.163.045-.16.046-.155.046-.152.048-.148.048-.143.048-.139.049-.136.05-.131.05-.126.051-.123.051-.118.051-.114.052-.11.052-.106.052-.101.052-.096.052-.092.052-.088.052-.083.052-.079.052-.074.051-.07.052-.065.051-.06.05-.056.05-.051.05-.023.025-.023.024-.021.024-.02.025-.019.024-.018.024-.017.023-.015.024-.014.023-.013.023-.012.023-.01.023-.01.022-.008.022-.006.023-.006.021-.004.022-.004.021-.001.021-.001.021.001.021.001.021.004.021.004.022.006.021.006.023.008.022.01.022.01.023.012.023.013.023.014.023.015.024.017.023.018.024.019.024.02.025.021.024.023.024.023.025.051.05.056.05.06.05.065.051.07.052.074.051.079.052.083.052.088.052.092.052.096.052.101.052.106.052.11.052.114.052.118.051.123.051.126.051.131.05.136.05.139.049.143.048.148.048.152.048.155.046.16.046.163.045.168.043.172.043.175.042.179.041.183.04.187.038.191.038.194.036.198.034.202.033.205.032.21.031.212.028.216.027.22.026.224.023.226.022.231.021.233.018.237.016.241.014.244.012.247.011.25.008.254.005.257.004.26.001.26-.001.257-.004.254-.005.25-.008.247-.011.244-.012.241-.014.237-.016.233-.018.231-.021.226-.022.224-.023.22-.026.216-.027.212-.028.21-.031.205-.032.202-.033.198-.034.194-.036.191-.038.187-.038.183-.04.179-.041.175-.042.172-.043.168-.043.163-.045.16-.046.155-.046.152-.048.148-.048.143-.048.139-.049.136-.05.131-.05.126-.051.123-.051.118-.051.114-.052.11-.052.106-.052.101-.052.096-.052.092-.052.088-.052.083-.052.079-.052.074-.051.07-.052.065-.051.06-.05.056-.05.051-.05.023-.025.023-.024.021-.024.02-.025.019-.024.018-.024.017-.023.015-.024.014-.023.013-.023.012-.023.01-.023.01-.022.008-.022.006-.023.006-.021.004-.022.004-.021.001-.021.001-.021-.001-.021-.001-.021-.004-.021-.004-.022-.006-.021-.006-.023-.008-.022-.01-.022-.01-.023-.012-.023-.013-.023-.014-.023-.015-.024-.017-.023-.018-.024-.019-.024-.02-.025-.021-.024-.023-.024-.023-.025-.051-.05-.056-.05-.06-.05-.065-.051-.07-.052-.074-.051-.079-.052-.083-.052-.088-.052-.092-.052-.096-.052-.101-.052-.106-.052-.11-.052-.114-.052-.118-.051-.123-.051-.126-.051-.131-.05-.136-.05-.139-.049-.143-.048-.148-.048-.152-.048-.155-.046-.16-.046-.163-.045-.168-.043-.172-.043-.175-.042-.179-.041-.183-.04-.187-.038-.191-.038-.194-.036-.198-.034-.202-.033-.205-.032-.21-.031-.212-.028-.216-.027-.22-.026-.224-.023-.226-.022-.231-.021-.233-.018-.237-.016-.241-.014-.244-.012-.247-.011-.25-.008-.254-.005-.257-.004-.26-.001-.26.001z'/%3e%3c/symbol%3e%3c/defs%3e%3cdefs%3e%3csymbol id='clock' width='24' height='24'%3e%3cpath transform='scale(.5)' d='M12 2c5.514 0 10 4.486 10 10s-4.486 10-10 10-10-4.486-10-10 4.486-10 10-10zm0-2c-6.627 0-12 5.373-12 12s5.373 12 12 12 12-5.373 12-12-5.373-12-12-12zm5.848 12.459c.202.038.202.333.001.372-1.907.361-6.045 1.111-6.547 1.111-.719 0-1.301-.582-1.301-1.301 0-.512.77-5.447 1.125-7.445.034-.192.312-.181.343.014l.985 6.238 5.394 1.011z'/%3e%3c/symbol%3e%3c/defs%3e%3cdefs%3e%3cmarker id='arrowhead' refX='7.9' refY='5' markerUnits='userSpaceOnUse' markerWidth='12' markerHeight='12' orient='auto-start-reverse'%3e%3cpath d='M -1 0 L 10 5 L 0 10 z'/%3e%3c/marker%3e%3c/defs%3e%3cdefs%3e%3cmarker id='crosshead' markerWidth='15' markerHeight='8' orient='auto' refX='4' refY='4.5'%3e%3cpath fill='none' stroke='black' stroke-width='1pt' d='M 1%2c2 L 6%2c7 M 6%2c2 L 1%2c7' style='stroke-dasharray: 0%2c 0%3b'/%3e%3c/marker%3e%3c/defs%3e%3cdefs%3e%3cmarker id='filled-head' refX='15.5' refY='7' markerWidth='20' markerHeight='28' orient='auto'%3e%3cpath d='M 18%2c7 L9%2c13 L14%2c7 L9%2c1 Z'/%3e%3c/marker%3e%3c/defs%3e%3cdefs%3e%3cmarker id='sequencenumber' refX='15' refY='15' markerWidth='60' markerHeight='40' orient='auto'%3e%3ccircle cx='15' cy='15' r='6'/%3e%3c/marker%3e%3c/defs%3e%3cg%3e%3crect x='601.5' y='146' fill='%23EDF2AE' stroke='%23666' width='300' height='37' class='note'/%3e%3ctext x='752' y='151' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='noteText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3e%3ctspan x='752'%3eGPUs: SGLang servers.%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect x='331.5' y='213' fill='%23EDF2AE' stroke='%23666' width='335' height='37' class='note'/%3e%3ctext x='499' y='218' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='noteText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3e%3ctspan x='499'%3e1. Document Parsing%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect x='331.5' y='378' fill='%23EDF2AE' stroke='%23666' width='570' height='37' class='note'/%3e%3ctext x='617' y='383' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='noteText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3e%3ctspan x='617'%3e2. Problem Splitting%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect x='331.5' y='543' fill='%23EDF2AE' stroke='%23666' width='1060' height='37' class='note'/%3e%3ctext x='862' y='548' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='noteText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3e%3ctspan x='862'%3e3. Solving Loop (per question)%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3cline x1='353' y1='590' x2='1370' y2='590' class='loopLine'/%3e%3cline x1='1370' y1='590' x2='1370' y2='987' class='loopLine'/%3e%3cline x1='353' y1='987' x2='1370' y2='987' class='loopLine'/%3e%3cline x1='353' y1='590' x2='353' y2='987' class='loopLine'/%3e%3cpolygon points='353%2c590 403%2c590 403%2c603 394.6%2c610 353%2c610' class='labelBox'/%3e%3ctext x='378' y='603' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='labelText' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eloop%3c/text%3e%3ctext x='886.5' y='608' text-anchor='middle' class='loopText' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3e%3ctspan x='886.5'%3e%5beach step until answer or max steps%5d%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg%3e%3crect x='52.5' y='1027' fill='%23EDF2AE' stroke='%23666' width='344' height='37' class='note'/%3e%3ctext x='225' y='1032' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='noteText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3e%3ctspan x='225'%3e4. Compile answer to PDF%3c/tspan%3e%3c/text%3e%3c/g%3e%3cg class='actor-man actor-top' name='U'%3e%3cline id='actor-man-torso0' x1='85' y1='52' x2='85' y2='72'/%3e%3cline id='actor-man-arms0' x1='67' y1='60' x2='103' y2='60'/%3e%3cline x1='67' y1='87' x2='85' y2='72'/%3e%3cline x1='85' y1='72' x2='101' y2='87'/%3e%3ccircle cx='85' cy='37' r='15' width='170' height='65'/%3e%3ctext x='85' y='94.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-man' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='85' dy='0'%3eUser%3c/tspan%3e%3c/text%3e%3c/g%3e%3ctext x='223' y='107' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eInput problems (PDF)%3c/text%3e%3cline x1='86' y1='136' x2='360' y2='136' class='messageLine0' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='fill: none%3b'/%3e%3ctext x='498' y='265' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eUpload PDF%3c/text%3e%3cline x1='365' y1='294' x2='630' y2='294' class='messageLine0' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='fill: none%3b'/%3e%3ctext x='501' y='309' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eMarkdown (text %2b images)%3c/text%3e%3cline x1='633' y1='338' x2='368' y2='338' class='messageLine1' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='stroke-dasharray: 3%2c 3%3b fill: none%3b'/%3e%3ctext x='615' y='430' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eRequest question boundaries%3c/text%3e%3cline x1='365' y1='459' x2='865' y2='459' class='messageLine0' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='fill: none%3b'/%3e%3ctext x='618' y='474' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eSplit into Q1%2c Q2%2c ...%3c/text%3e%3cline x1='868' y1='503' x2='368' y2='503' class='messageLine1' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='stroke-dasharray: 3%2c 3%3b fill: none%3b'/%3e%3ctext x='615' y='640' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eSpawn N parallel branches (reason %2b pick tools)%3c/text%3e%3cline x1='365' y1='669' x2='865' y2='669' class='messageLine0' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='fill: none%3b'/%3e%3ctext x='743' y='684' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eCreate a sandbox per branch%3c/text%3e%3cline x1='365' y1='713' x2='1120' y2='713' class='messageLine0' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='fill: none%3b'/%3e%3ctext x='618' y='728' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eTool calls%3c/text%3e%3cline x1='868' y1='757' x2='368' y2='757' class='messageLine1' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='stroke-dasharray: 3%2c 3%3b fill: none%3b'/%3e%3ctext x='860' y='772' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eExecute Science tools%3c/text%3e%3cline x1='365' y1='801' x2='1355' y2='801' class='messageLine0' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='fill: none%3b'/%3e%3ctext x='863' y='816' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eExecution output%3c/text%3e%3cline x1='1358' y1='845' x2='368' y2='845' class='messageLine1' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='stroke-dasharray: 3%2c 3%3b fill: none%3b'/%3e%3ctext x='618' y='860' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eCandidate solutions (peer-reviewed)%3c/text%3e%3cline x1='868' y1='889' x2='368' y2='889' class='messageLine1' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='stroke-dasharray: 3%2c 3%3b fill: none%3b'/%3e%3ctext x='615' y='904' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eCritic ranks branches%3c/text%3e%3cline x1='365' y1='933' x2='865' y2='933' class='messageLine0' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='fill: none%3b'/%3e%3ctext x='618' y='948' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eBest Solution%3c/text%3e%3cline x1='868' y1='977' x2='368' y2='977' class='messageLine1' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='stroke-dasharray: 3%2c 3%3b fill: none%3b'/%3e%3ctext x='226' y='1079' text-anchor='middle' dominant-baseline='middle' alignment-baseline='middle' class='messageText' dy='1em' style='font-family: arial%2c sans-serif%3b font-size: 16px%3b font-weight: 400%3b'%3eOutput final solution (PDF)%3c/text%3e%3cline x1='363' y1='1108' x2='89' y2='1108' class='messageLine1' stroke-width='2' stroke='none' marker-end='url(%23arrowhead)' style='stroke-dasharray: 3%2c 3%3b fill: none%3b'/%3e%3cg class='actor-man actor-bottom' name='U'%3e%3cline id='actor-man-torso5' x1='85' y1='1163' x2='85' y2='1183'/%3e%3cline id='actor-man-arms5' x1='67' y1='1171' x2='103' y2='1171'/%3e%3cline x1='67' y1='1198' x2='85' y2='1183'/%3e%3cline x1='85' y1='1183' x2='101' y2='1198'/%3e%3ccircle cx='85' cy='1148' r='15' width='170' height='65'/%3e%3ctext x='85' y='1205.5' dominant-baseline='central' alignment-baseline='central' class='actor actor-man' style='text-anchor: middle%3b font-size: 16px%3b font-weight: 400%3b font-family: arial%2c sans-serif%3b'%3e%3ctspan x='85' dy='0'%3eUser%3c/tspan%3e%3c/text%3e%3c/g%3e%3c/svg%3e)
Overview
The system ran in six main steps:
- OCR: The exam PDF is translated into a JSONL file.
- Preprocessing: Figures are captioned with a vision-capable LLM.
- Branched solve: Multiple reasoning branches are generated across all questions.
- Self-verification: The LLM audits its own solutions in a Python sandbox.
- Peer review: A panel of 11 agents reviews solutions, each enforcing a single constraint.
- Typesetting: The final solution PDF is produced through LaTeX.
Processing the input
Our system operated directly on the scanned exam PDF. Therefore, we first converted the exam PDF into a structured JSONL representation using open-source OCR models. Then, we used a vision-capable LLM to caption figures and attach descriptions that are more suitable for downstream text-only reasoning.
Not betting everything on a single pass
For each question, the solver then generated multiple branches of reasoning. A separate arbiter agent selected the strongest branch so far, pruning the remaining branches.
In the real IPhO run, three branches were generated per question, which led to the best balance between accuracy and speed. Internal experiments with one to five branches showed that fewer branches destabilized accuracy, whereas more branches overwhelmed the arbiter and excessively delayed answer generation.
A sandboxed environment for each branch
Each reasoning branch then received disposable Linux microVMs, where the agent could verify its work by writing and executing Python code. This ensured that one branch’s state could never contaminate another’s, and freely allowed the execution of unstrusted code without risk to the host.
Adversarial peer review
We then ran a panel of critic sub-agents, each responsible for one axis among eleven evaluation criteria:
- Math formatting: Every displayed equation and final answer is wrapped in proper math delimiters.
- Requested figures: The solution includes a sketch or plot if requested.
- Completeness: No sub-part is skipped or left partially answered.
- Case notation: Conditions in piecewise expressions are correctly parenthesized.
- Variable discipline: All variables are defined, and no variable misuse arises from unrelated sub-questions.
- Numerical evaluation: A final answer is reduced to a single number if possible.
- Dimensional consistency: The units on both sides of every derived equation match.
- Sign convention: Change is computed as the final value minus the initial value instead of the reverse.
- Algebraic integrity: No constant or factor is dropped or introduced across a derivation.
- Significant figures: Final numerical answers carry a precision consistent with the least-precise given datum.
- Derivation integrity: The final expression follows from the solution’s own complete derivation, and does not appeal to a “standard” or “known” result. Derivation integrity was necessary because IPhO grading may penalize the use of memorized formulas that are not considered standard results.
Here, every sub-agent must approve before a result is accepted. If any critic is uncertain, the reasoning branch failed, and the pipeline continuously repeated generation until peer review passed.
The system’s output
Our system scored 28.6 points out of 30, a loss of 1.4 points. Below is the system’s actual full output, along with the specific locations where the official graders deducted points.
The 1.4-point deduction
Decomposing the deductions, 1.3 points were lost in T2-A1, and 0.1 point was lost in T3-C3.
- In T2-A1, the system made extensive use of the given sandboxing tool and performed a numerical simulation. While the answer was correct, the IPhO grader stated that such a numerical simulation was not a feasible solution for human solvers. Therefore, only 0.2 points were awarded out of 1.5.
- In T3-C3, the system computed and stated the correct final value with the correct number of significant figures. But the model then added extra subtext, justifying why the answer had 2 significant figures. The model attributed the significant-figure count to the second term of the final arithmetic operation, when it was the first term that determined it. As a result, 0.7 points were awarded out of 0.8.
In both cases, our system found the correct answers, but was deducted points due to solution-method feasibility and incorrect justifications.
Notes
In T2-B2, our model developed an alternative solution that bypassed the intermediate checkpoints at which the official solution awards partial marks. The bypass resulted in a 1.3-point loss, as it failed to show the checkpoints defined in the official marking schema. However, the model’s solution was accepted as an alternative with no logical gaps during the moderation session, receiving full marks.
Our takeaway
To us, the IPhO result complements what we saw with Thyla. There, an agentic system built on open-weight models showed that it could make progress on open-ended research tasks, where choosing what to try is a critical part of the pipeline. By comparison, here we tested the same general approach using a more direct measure of technical problem-solving. A score of 28.6 out of 30 suggests that constructing agentic systems around weaker models can still perform at the frontier level, even when the task primarily tests raw reasoning ability.
What matters most to us is that this performance did not come solely from the base model. Better models will continue to matter, but we believe that there is still substantial capability to be gained from system design itself. Taken together with Thyla, this result strengthens our conviction that the frontier is not defined by model weights alone, and that open-weight models can already support systems that operate well beyond their standalone capabilities.